Ecommerce image testing means running a controlled experiment between two product image treatments and measuring which one sells more. The method is simple. The blocker is sample size. At a 2.5% baseline conversion rate, detecting a 10% relative lift needs roughly 64,000 sessions per variant, which is more traffic than many product pages see in a year.
That gap explains why the published wins are so large. A test that stops as soon as one variant is ahead can report a big lift on a few hundred sessions. The same test, run again, can report a loss. Both reports are noise. Neither is a result you can put in a catalog plan.
This guide covers what the research on AI imagery measured, the session counts each level of lift requires, the three routes open to you depending on your traffic, and what to measure when conversion rate alone will not move enough to read.
Key Takeaways
-
Run the sample-size math before the test, not after. At a 2.5% baseline, a 10% relative lift needs about 64,000 sessions per variant. A 30% lift needs about 7,800. Below those counts you are reading noise.
-
The Alibaba study measured something else. Its 13% CTR and conversion gains compared AI-generated product designs against human-designed products, not AI photography against studio photography of the same item.
-
Big published lifts are a symptom of small samples. Underpowered tests only ever surface large effects, so the wins that get written up are the ones least likely to replicate.
-
Test at the ad layer when the PDP cannot carry it. Paid social buys you tens of thousands of impressions in days at a cost you control. Product pages take months to reach the same count.
-
Measure add-to-cart, not just conversion. It sits higher in the funnel, so it has a bigger baseline, so it needs a smaller sample to read.
-
Change one thing. Model versus flat lay is a test. New model plus new background plus new crop is a redesign with no attributable cause.
-
The EU disclosure rules have applied since 2 August 2026. Article 50 of the AI Act asks tool makers to mark AI output and brands to label deep fakes, so a synthetic human carries more weight than a plain product still.
What is ecommerce image testing?
Ecommerce image testing is a controlled comparison between two or more product image treatments, where visitors are split at random and each group sees one treatment. Everything else on the page stays fixed. You measure a commercial outcome, usually add-to-cart rate or purchase conversion rate, and you decide whether the difference between groups is larger than the variation you would expect from chance alone.
The last clause is the whole discipline. Two identical images shown to two random groups will produce different conversion rates, because visitors differ. A test is valid only when it can tell a real difference apart from that background wobble, and that ability is set entirely by how many sessions you collect.
What the research on AI imagery measured
One statistic in this category says AI visuals delivered over 13% relative improvements to click-through and conversion rate, plus a 7.9% drop in returns. It is real, and the paper was accepted at KDD 2026.
It does not show that AI photography beats studio photography.
The paper is “Sell It Before You Make It: Revolutionizing E-Commerce with Personalized AI-Generated Items”, deployed at Alibaba and accepted by the KDD 2026 ADS Track (arXiv:2503.22182, September 2026). What it compares is AI-generated fashion items against human-designed items. Merchants described a garment in text. The system generated the design and a photorealistic image of it on a digital model. The listing went live before the garment was manufactured, and production started only once orders arrived.
So the 13% is a design and assortment result. The AI arm had different products in it, chosen by a preference-alignment model trained on shopper behavior. Attributing that lift to the photography is reading past the variable that moved.
This matters beyond pedantry. If you quote that number to justify swapping your packshots for AI renders, you have imported an effect size from an experiment that did not run your test. Your expected lift is unknown, and planning a test around an imported 13% will size it wrong.
The honest position: AI imagery is a production-cost and throughput decision with a conversion effect that is unmeasured on your catalog until you measure it. That is a reason to run the test properly.
If the decision is about throughput, size it with the first-pass acceptance rate, not the price per image. The review arithmetic behind AI fashion photography at scale shows why review labor becomes the largest cost well before generation spend does. The AI image retry rate turns a first-pass rate into generations per usable image.
The traffic math for an image test
Sample size comes from four inputs: your baseline conversion rate, the smallest lift worth detecting, your confidence level, and statistical power. Fix confidence at 95% and power at 80%, which are the standard settings, and the rest is arithmetic.
Littledata benchmarked 2,800 Shopify stores in 2023 and found an average conversion rate of 1.4%, with the best 20% of stores above 3.2% (littledata.io, September 2026). Category figures differ between sources, because some measure sessions to orders and others measure visitors to orders. Pull your own baseline from your analytics rather than borrowing one. The table below works at 2.5%, a rate a well-run apparel store can reach.
| Relative lift you want to detect | Conversion rate moves | Sessions per variant | Total sessions |
|---|---|---|---|
| 10% | 2.50% to 2.75% | ~64,000 | ~128,000 |
| 13% (the Alibaba figure) | 2.50% to 2.83% | ~38,000 | ~77,000 |
| 20% | 2.50% to 3.00% | ~17,000 | ~34,000 |
| 30% | 2.50% to 3.25% | ~7,800 | ~15,600 |
| 50% | 2.50% to 3.75% | ~3,000 | ~6,100 |
Computed with the standard two-proportion sample size formula at 95% confidence and 80% power. Run your own baseline through any published calculator and you will land in the same place.
Read the table from the bottom up and the publishing bias becomes obvious. A store with 6,000 sessions to spend can only ever detect a 50% swing. If the true effect is 12%, that store will not find it. Sometimes random variation produces a big number, and then the store reports a huge win. Underpowered tests tend to produce large wrong answers.
We found no published benchmark for how much an image change lifts an established catalog, as of September 2026. Plan for a small effect. Small effects are the ones the table says are hardest to measure. They are also where the decision matters, because a 10% lift across a catalog is a serious number.
Three routes, chosen by your traffic
Check your analytics for sessions per month on the product pages you would test. Then pick the route that matches.
Above roughly 30,000 sessions per month on the test set. Run the PDP test properly. Two variants, one variable, a fixed duration set in advance, and no peeking at the result to decide when to stop. Expect four to eight weeks. Measure add-to-cart as the primary metric and purchase conversion as the secondary.
Between roughly 5,000 and 30,000. Do not test on the PDP. You can detect only very large effects, and the honest reading of a null result will be that you learned nothing. Move the test to the ad layer, covered next, and use the winner to decide the catalog treatment.
Below roughly 5,000. Skip conversion testing entirely for now. Traffic is your constraint. Use AI imagery to fill the ecommerce product photography shots you currently do not have at all: the in-scale frame, the detail crop, the in-use shot, the missing variant colorways. Coverage beats optimization when the sample is this thin. The PDP image order that answers a shopper’s questions in sequence is a better use of the effort than a test you cannot read.
Sorting your catalog by which products in your catalog are underserved tells you where to point that effort first. Tightening the listing text costs no traffic at all, and the three versions each product needs is the cheapest fix available at this volume.
Test at the ad layer when the PDP cannot carry it
Paid social solves the sample-size problem by letting you buy the sample. A modest budget delivers tens of thousands of impressions in days, and the platform splits traffic for you.
The tradeoff is honest and worth stating. Ad-layer results measure attention in a feed, not purchase intent on a product page. A thumb-stopping image can win on click-through and lose on conversion. Treat the ad test as a fast screen that narrows six candidate treatments to two, then take those two to the PDP if your traffic supports it.
The ad layer has its own readability trap. Loading nine variants into a single ad set hands the allocation decision to the platform’s optimizer, so the report tells you where spend went rather than which image won.
Set it up this way:
- Hold the copy identical across variants. Same headline, same primary text, same call to action. The image is the only difference.
- Run one variable per test. On-model against flat lay. Studio white against a styled scene. One model appearance against another. Not all three at once. If the variable you are weighing is a generated model against a photographed one, decide that shot by shot rather than catalog-wide before you spend traffic on it.
- Give each variant its own ad set with an equal budget cap, so the platform’s optimizer cannot starve one arm before it collects data. Better still, use the platform’s own experiment tool, since most ad creative tests cannot be read once delivery has allocated spend unevenly.
- Read click-through rate first, cost per add-to-cart second. Click-through moves fastest and has the largest baseline, so it reaches significance soonest.
- Run at least seven full days to cover the weekly cycle. Weekend and weekday shoppers behave differently.
What to measure, and why conversion rate is the wrong primary
Conversion rate is the number you care about. It is also the worst one to test on, because it sits at the bottom of the funnel where the baseline is small and the sample requirement is large.
Move your primary metric up the funnel and the math improves immediately. Add-to-cart rate is higher than purchase rate on the same page, because many shoppers add an item and do not buy. A larger baseline needs fewer sessions to detect the same relative change, which can cut a test from months to weeks.
| Metric | Where it sits | Why use it |
|---|---|---|
| Image gallery interaction | Top | Largest baseline, reads in days, but weakest link to revenue |
| Add-to-cart rate | Middle | Best primary metric for image tests: big enough baseline, close enough to intent |
| Purchase conversion rate | Bottom | The real goal, but slow and sample-hungry. Use as secondary |
| Return rate | Post-purchase | The one that catches an image promising something the product does not deliver |
Return rate deserves its own note. An image treatment can lift conversion and lift returns at the same time, and the net is a loss. That is the failure mode of imagery that flatters a product. It is why checking AI product photo accuracy before you ship belongs before any conversion test. Track returns on the tested SKUs for a full return window before you call a winner.
Produce the variants so only one thing changes
A test is only as clean as the assets. If your control is a two-year-old studio shot and your variant is a fresh render with a different crop, different lighting, and a different background, you have compared two eras of your brand, not two image treatments.
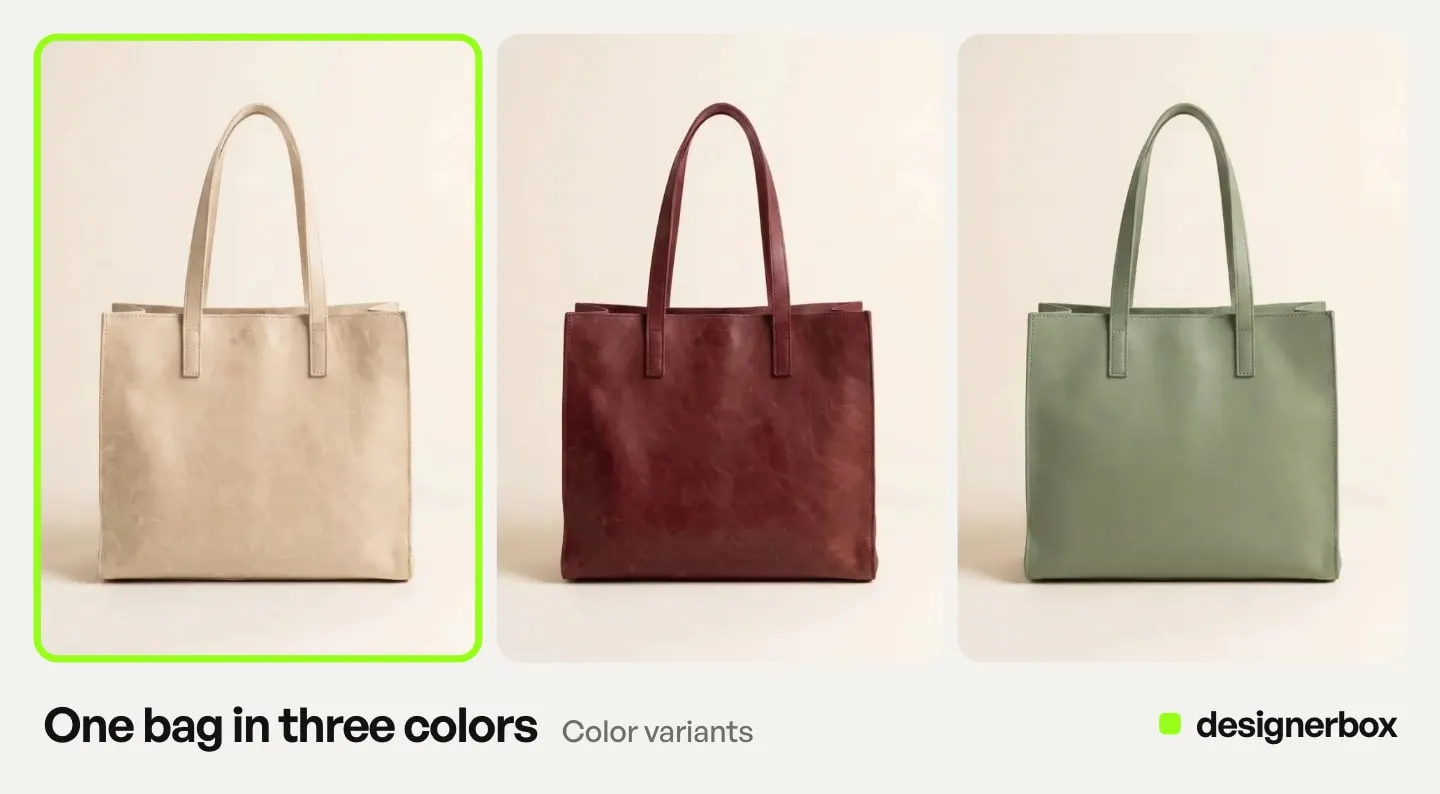
Generate both arms from the same source photo of the real product, and change exactly one attribute between them. That is the practical case for producing variants from your own product image rather than commissioning two separate shoots: the source is held constant by construction.
In DesignerBox that runs through AI product photography. One product photo is the input for the packshot, the styled scene and the on-model shot. Each model costs a different amount, so there is no flat price for an image. The cost of a run is shown before the run, so you pick the model against that number. The Ad versions with new headlines template and the Versions of an ad app make the variant set a test needs in one run. Analyze ad in Create reviews a finished ad on hook, offer and brand fit before you test it.
Uploading your own photos and the commercial license start on the Pro plan, which is the plan to be on before a variant goes live on a store. Plans are on the pricing page. DesignerBox makes the test arms and the winning treatment. Your store or your ad platform runs the test, so you download the results and upload them there. For a store that adds products every week, see DesignerBox for ecommerce brands.
Once a treatment wins, save it as a workflow and run it again on the next product. That is the point of a validated result: you settle the question once on 20 SKUs, then apply the answer to the rest without arguing it again at every launch.
The test is the expensive part and you pay it once. The rollout should be mechanical. The workflow reads the same settings on every product after that. The brand sits in a brand profile, and the workflow reads it on every run. The hundredth product then keeps the look the test proved. To hold the winner and change one thing at a time, see producing ad variants at scale.
For the cost comparison that usually sits behind this decision, see what a product photoshoot costs.
Disclosure since 2 August 2026
Test design is not the only constraint. Article 50 of the EU AI Act has applied since 2 August 2026. It asks providers of AI systems that generate synthetic content to mark the output in a machine-readable format, so it is detectable as artificially generated (European Commission, September 2026). Tool makers whose systems were on the market before 2 August 2026 have until 2 December 2026 to add those marks. That grace period covers the marking duty only.
Two practical points. The marking duty falls on the providers of the generation systems, not on every merchant using them, while the brand-side duty is to disclose a deep fake it publishes. And the exposure is uneven: a realistic synthetic human wearing your product carries more disclosure weight than a plain still of the product on a sweep.
Verify your specific obligations against the regulation and your marketplace’s own policy before you scale a treatment across a catalog. This is general information, not legal advice.
FAQ
How long should an ecommerce image test run?
Long enough to hit the sample size you calculated, and never less than seven full days. Set the duration in advance and do not stop early because one variant is ahead. Stopping when a result looks good is how underpowered tests produce fake wins.
Can I test AI product images if I only get 3,000 sessions a month?
Not on the product page. At that volume you can only detect swings above roughly 50%, which image treatments rarely produce. Use AI imagery to fill missing shots instead, or move the test to paid social where you can buy the sample size directly.
Do AI product images convert better than studio photography?
There is no general answer, and the Alibaba study behind the 13% figure measured AI-generated product designs rather than AI photography of existing products. The effect on your catalog is unmeasured until you measure it. Treat AI imagery as a throughput and cost decision first, with conversion as a hypothesis you test.
What is a realistic lift to expect from changing product images?
We found no published benchmark for an established catalog with competent photography, as of September 2026, so plan for a small effect. Larger effects are more likely where the starting point is poor: missing shots, low resolution, or no in-use frame at all.
Should I test add-to-cart rate or conversion rate?
Add-to-cart, as the primary. Its baseline is larger than purchase conversion, so it reaches statistical significance on fewer sessions. Track purchase conversion as the secondary metric and check return rate before you call a winner.
Do I need to disclose AI-generated product images?
Sometimes. In the EU, Article 50 of the AI Act has applied since 2 August 2026. It asks tool makers to mark AI output, and it asks brands to label a deep fake they publish. A realistic synthetic human carries more disclosure weight than a plain product still. Rules also differ by market and marketplace, so check the regulation and your marketplace’s current policy directly.
Can I test more than two image variants at once?
You can, but each additional arm splits your traffic and raises the sample size needed to keep the same confidence. At the traffic levels most stores run, two arms is the practical limit on a product page. Multi-arm testing belongs on the ad layer where impressions are purchasable.
Sources
All read in September 2026.
- The Alibaba study behind the 13% click-through and conversion figures and the 7.9% return drop, and what it compared: “Sell It Before You Make It: Revolutionizing E-Commerce with Personalized AI-Generated Items”, accepted by the KDD 2026 ADS Track: arXiv:2503.22182, read September 2026
- Shopify average conversion rate and the top-20% figure, from 2,800 Shopify stores benchmarked in 2023: littledata.io, read September 2026
- EU AI Act Article 50 transparency obligations, the 2 August 2026 application date and the grace period to 2 December 2026 for the provider marking duty: European Commission FAQ, read September 2026
- DesignerBox plans, credits and feature gating: DesignerBox pricing page (designerbox.ai/pricing), September 2026
Sample sizes computed with the standard two-proportion formula at 95% confidence and 80% power. Research claims verified against arXiv:2503.22182 and Littledata’s Shopify conversion benchmark as of September 2026, and the EU transparency obligations against the European Commission’s Article 50 FAQ in September 2026. This is general information, not legal advice. Individual results vary.